|
Kohsuke Ide I'm a Research Assistant at AIST and a Master's student in Computer Science at University of Tsukuba, where I work at Satoh Lab. My research focuses on visual world models, 3D understanding, vision-language models, and diagnostic evaluation. I received my B.Sc. in Applied Mechanics and Aerospace Engineering (Minor: Computer Science) from Waseda University. Previously, I worked at Preferred Networks on 3D reconstruction and free-viewpoint video technologies. |

|
ResearchI'm interested in computer vision, 3D understanding, and vision-language models. My research focuses on learning 3D representations and understanding spatial relationships using large language models. Some papers are highlighted. |
|
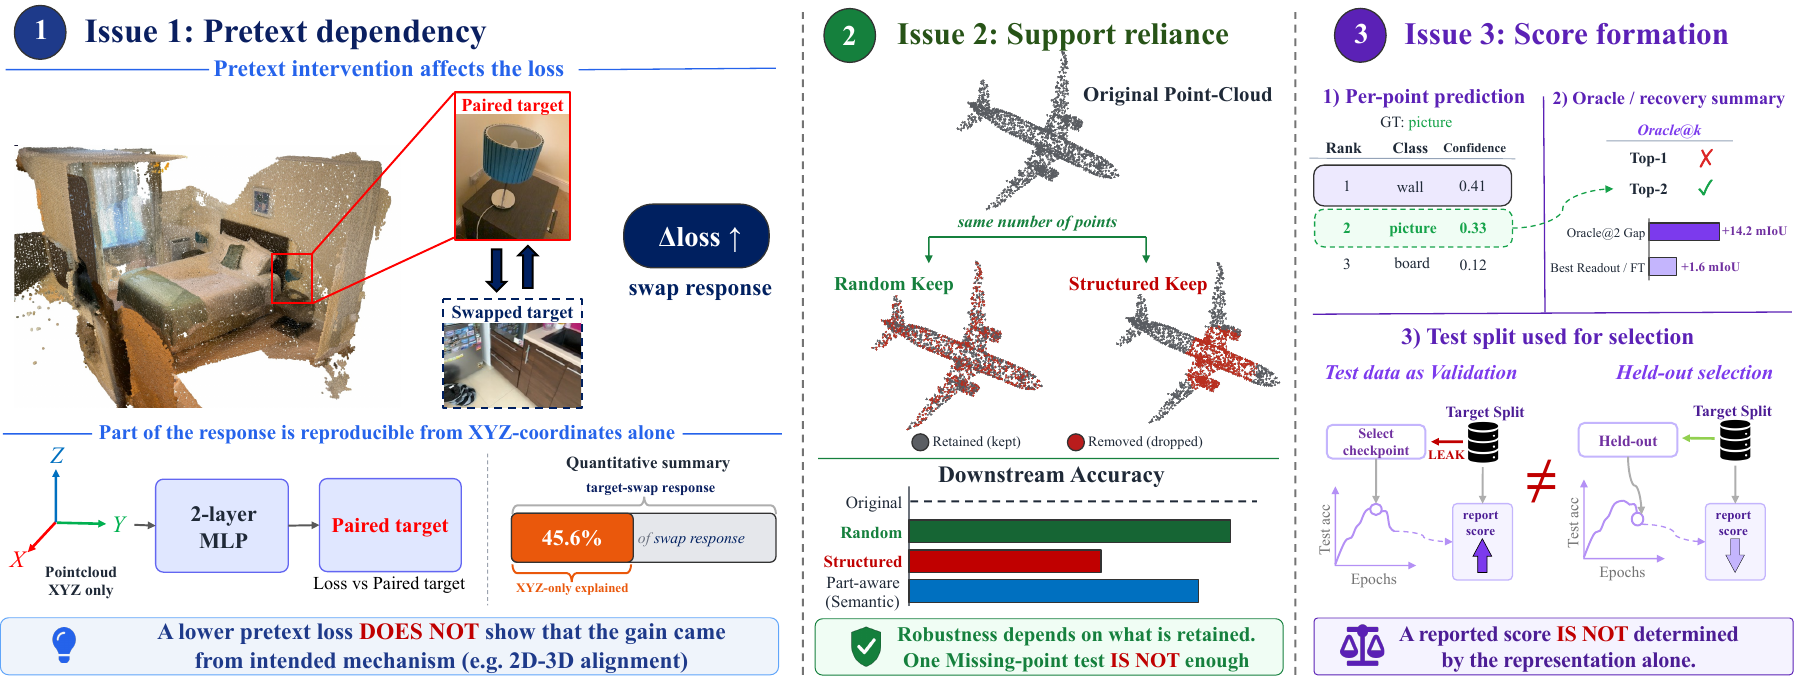
Beyond Downstream Scores: Controlled Diagnostics for Point-Cloud Self-Supervised Learning Evaluation
Kohsuke Ide, Ryousuke Yamada, Yue Qiu, Yoshihiro Fukuhara, Hirokatsu Kataoka, Yuki M. Asano, Yutaka Satoh Conference on Neural Information Processing Systems (NeurIPS), 2026 (E&D Track) Spotlight (top 1.28%; 48 oral/spotlight papers out of 3,757 submissions) Controlled diagnostics for identifying what point-cloud self-supervised learning methods learn beyond downstream benchmark scores. |

|
Beyond Single Object: Learning 3D Relations with Large Language Models
Kohsuke Ide, Ryousuke Yamada, Yue Qiu, Xianzheng Ma, Yoshihiro Fukuhara, Hirokatsu Kataoka, Yutaka Satoh The IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) Findings, 2026 project page / arXiv / code / press release (jp) / press release (en) Investigating how large language models can learn and reason about 3D spatial relationships between multiple objects. |

|
3D sans 3D Scans: Scalable Pre-training from Video-Generated Point Clouds
Ryousuke Yamada, Kohsuke Ide, Yoshihiro Fukuhara, Hirokatsu Kataoka, Gilles Puy, Andrei Bursuc, Yuki M. Asano The IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026 project page / arXiv / code Scalable 3D pre-training approach that generates point clouds from videos, eliminating the need for expensive 3D scans. |
|
VGI
White Paper
|
Visual General Intelligence: A White Paper
Hirokatsu Kataoka, Yoshihiro Fukuhara, Yonglong Tian, Shangzhe Wu, Oishi Deb, Ryousuke Yamada, Christian Rupprecht, Jianyuan Wang, Kohsuke Ide, Koichi Namekata, Xianzheng Ma, Yiming Chen, Robert Geirhos, Aditi Raghunathan, Yuki M. Asano, Deva Ramanan, David Fouhey, Andrew J. Davison, Yilun Du, Jiajun Wu, Zhuang Liu Preprint, 2026 arXiv Reconsidering intelligence from a vision-centered perspective and outlining research directions toward visual general intelligence. |

|
Seeing Red, Thinking Bad: Color Bias in Vision Language Models
Kohsuke Ide, Ryousuke Yamada, Yoshihiro Fukuhara, Hirokatsu Kataoka, Yutaka Satoh International Conference on Pattern Recognition (ICPR), 2026 project page / arXiv / blog / code Investigating how color biases in vision language models affect their reasoning and decision-making. |

|
Colors You Can't See, Semantic Biases You Can't Ignore
Kohsuke Ide, Ryousuke Yamada, Yoshihiro Fukuhara, Hirokatsu Kataoka, Yutaka Satoh The IEEE/CVF International Conference on Computer Vision (ICCV) Workshop on MMRAgI, 2025 Studying the sensitivity of vision-language models to visual styling of text. |
Invited Talks
Seeing What Matters, Learning How to Find Out: Toward Visual General Intelligence |
Blog |
|
Intelligence Learns How to Find Out
Plato Is Not a Space
Where Do Good Vision Targets Come From?
Color as a Presentation Variable |
Experience |
|
National Institute of Advanced Industrial Science and Technology (AIST)
Preferred Networks (PFN)
LightBlue Technology
M3 |
Awards & Projects |
|
MIRU 2025 Interactive Presentation Award (Top 4%) - "Can 3D Large Language Models Count to Three?" Winner of 2023 Hackathon at WINC - Pushups Counter: Work out helper using computer vision for edge device. |
Academic Service |
|
Workshop Organizer - Workshop on Visual General Intelligence: Vision Research Toward the AGI Era, CVPR 2026
Organizer - LENS (Young Researchers in Vision)
|
|
Template from Jon Barron's website. |